1. Pick a photo
Sign in and choose a photo of one person, then confirm it is you or that they agreed.
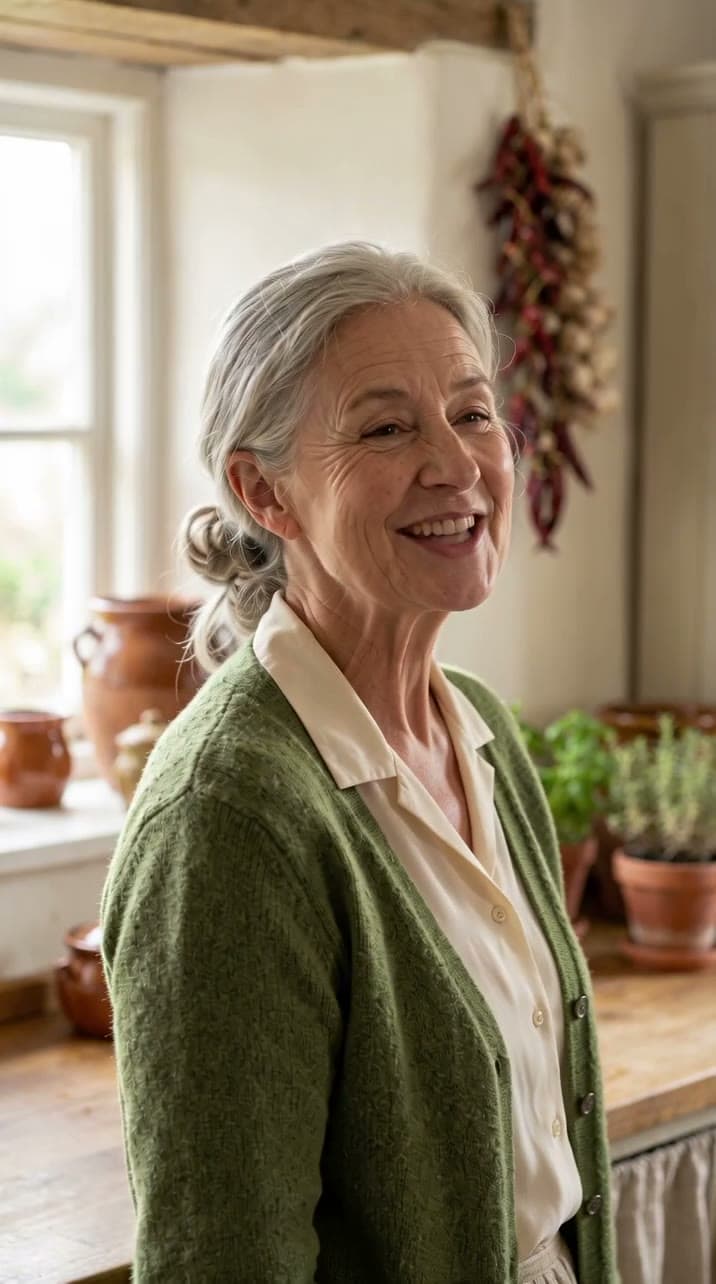
OmniHuman v2 takes a single photo and an audio track and draws the person speaking it. The lips follow the words; the head, the brows and the hands follow how they are said.
A voiceover, an interview answer or a verse of a song all drive it the same way. The clip is exactly as long as the audio.
An optional prompt sets the scene, the movement and the camera: a slow push in, a turn to the window, a laugh at the end.
A still of one person, 300 to 6000 pixels a side, from a tall portrait to a wide frame.
A recording you upload (.mp3 or .wav), or a script the studio reads aloud for you first.
On Phantra, a script is voiced by ElevenLabs v3 in one of 21 voices, and you hear it before the clip.
Mouth shapes, expressions, head turns and gestures, all timed to the sound.
Scene, movement and camera in a line. Written in English, Chinese, Japanese, Korean, Spanish or Indonesian.
The model takes up to 300 seconds; Phantra makes 30 seconds on Standard, 60 seconds on Pro, 120 seconds on Max.
Billed on the length of the voice, rounded up to the whole second, and shown on the card before it runs.
An upload, a still you made in the studio or one of your saved elements.
The clip is a render like any other: upscale it, reframe it or cut it with other clips.
What an OmniHuman v2 clip costs on Phantra, in credits. One rate per second of voice, so the price depends only on its length.
| Clip | Credits |
|---|---|
| 10-second clip | 252 |
| 30-second clip | 756 |
| 60-second clip | 1,512 |
| 120-second clip | 3,024 |
Sign in and choose a photo of one person, then confirm it is you or that they agreed.
Upload a recording, or type a script, choose a voice and listen to the preview.
The card shows the credits for the voice's length. Approve it and the clip lands in your Library.
Type the words or upload them, hear the voice, then approve the clip at the price on the card.